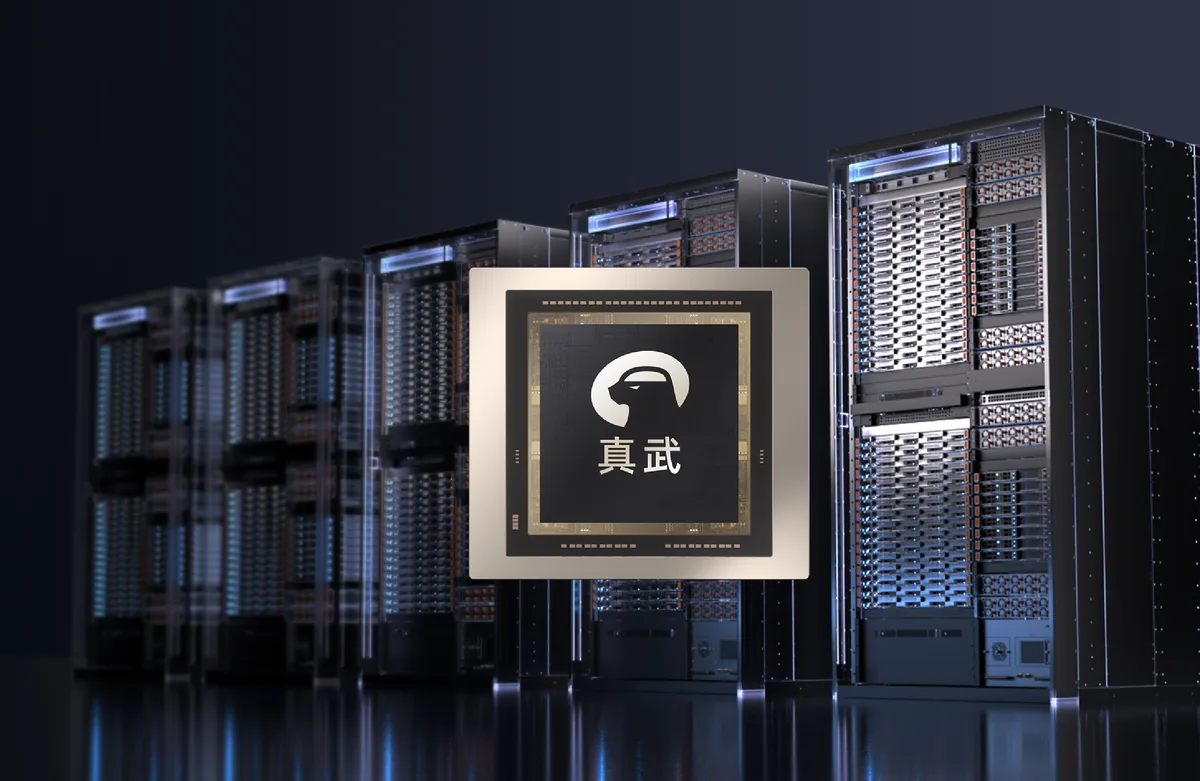
Zhenwu M890 All-Scenario Training & Inference AI Chip
Product in T-Head's official AI-chip section. End-to-end self-developed hardware; upgraded self-developed parallel-compute architecture and on-chip interconnect. The self-developed T-Head SAIL® software stack has independent IP, is compatible with mainstream AI ecosystems, provides a unified programming API and requires no application-code modification for migration; supports multi-process resource sharing and multi-tenant isolation; chip compute is bundled with Alibaba AI frameworks, platforms, models and applications. Official specs: 144 GB memory; 800 GB/s inter-chip interconnect; FP8/FP4...
Key Highlights
- Fully self-developed
- high performance (144 GB memory, 800 GB/s interconnect, FP8/FP4, 64-card full-bandwidth mesh)
- easy to use (SAIL® full stack, unified API, zero-code migration)
- flexible deployment (multi-process sharing, tenant isolation)
- chip-cloud-model integration
Technical Specifications
| Memory Capacity | 144 GB |
|---|---|
| Inter-chip Bandwidth | 800 GB/s(ICN,8 端口直连 / 8 ICN ports direct) |
| Low Precision | FP8 / FP4(另支持 FP32/BF16/FP16/INT8 / also FP32/BF16/FP16/INT8) |
| Interconnect Scale | ICN Switch 64 卡全带宽互联 / 64-card full-bandwidth mesh |
| Software Stack | T-Head SAIL®(统一 API,兼容主流 AI 生态 / unified API, mainstream AI ecosystem compatible) |
| Process, TDP, Form Factor | 官网未公布 / not disclosed |
Typical Use Cases
官网公开为芯片级规格(显存/互联带宽/精度),未公布板卡形态、TDP、制程工艺与公开 PDF datasheet(页面“完整 Datasheet”需商务合作/技术工单获取);产品通过阿里云生态与合作渠道交付,非公开零售加速卡;图片为官网产品页主视觉渲染图(芯片 die 与数据中心机柜);category 取 accelerator_card(AI 加速芯片产品线),实际交付形态以官方云实例/商务方案为准。本地图片为官网产品页主视觉的产品区域裁剪版(裁剪掉左侧空白),原始图见 image_source_urls。
Related Products
Atlas 300I A2 Inference Card
High-performance AI inference card integrated into servers View details →
Atlas 300I Pro Inference Card
Inference accelerator card integrated into servers View details →
Atlas 300I Duo Inference Card
Dual-chip high-density inference accelerator card View details →