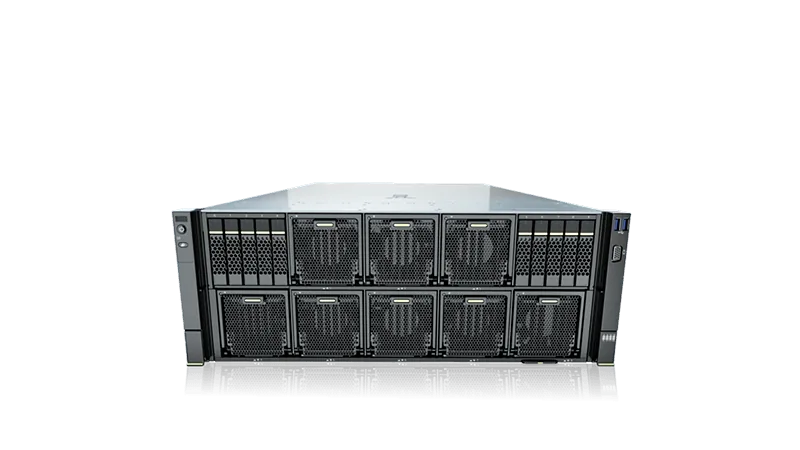
Huawei Atlas · Compute Server
Atlas 800I A2 Inference Server
The Atlas 800I A2 inference server uses an 8-modular efficient inference design with NPU interconnect for generative LLM inference such as intelligent customer service, copywriting generation and knowledge accumulation.
Key Highlights
- 8-modular efficient inference
- strong compute, memory bandwidth and interconnect
- NPU interconnect for higher LLM inference efficiency.
Technical Specifications
| Form Factor | 4U AI server |
|---|---|
| CPU | Kunpeng 920 x4 |
| System Memory | 32x DDR4 DIMM slots up to 3200MT/s |
| Internal Interconnect | optional full NPU mesh, 392GB/s aggregate |
| External Network | 8x 200GE QSFP RoCE |
| PCIe | up to 3x PCIe 4.0 |
| PSU | 4x 2.6kW, 2+2 |
| Cooling | air-cooled |
| Module model & total compute | 官网未公开 |
Typical Use Cases
Generative LLM inference: intelligent customer service, content generation and knowledge base scenarios.
翻译稿;官网未公开8个推理模组的具体型号、HBM容量与整机TOPS算力;img1: main; 资料链接为官网《Atlas 800I A2推理服务器技术白皮书》落地页。
Related Products
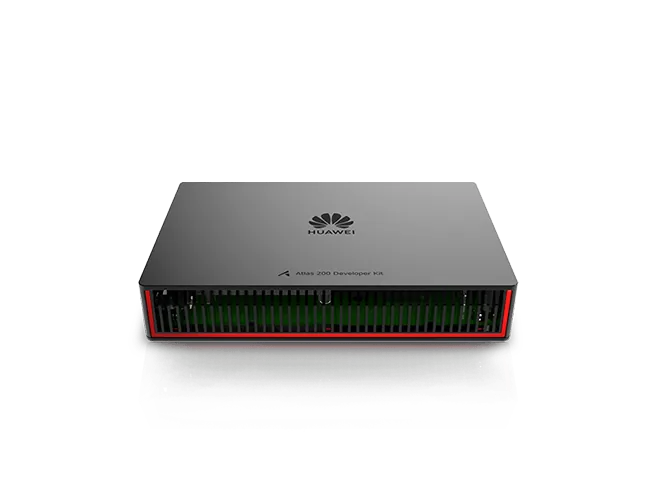
Huawei Atlas
Atlas 200I DK A2 Developer Kit
Easy-to-use AI development kit for fast innovation View details →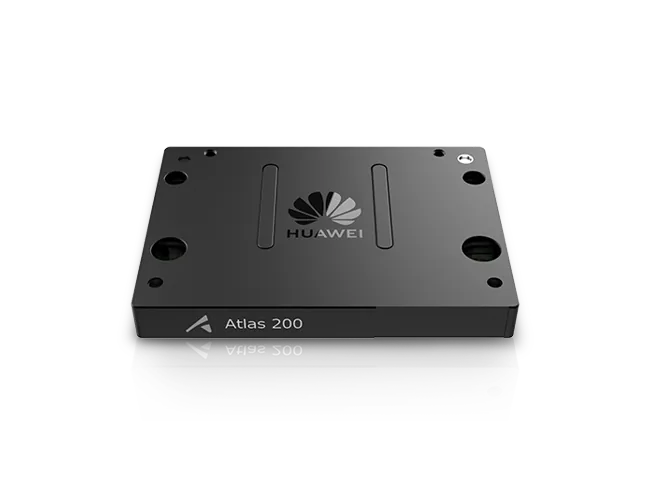
Huawei Atlas
Atlas 200I A2 Acceleration Module
Edge AI accelerator module embedded in smart devices, robots and drones View details →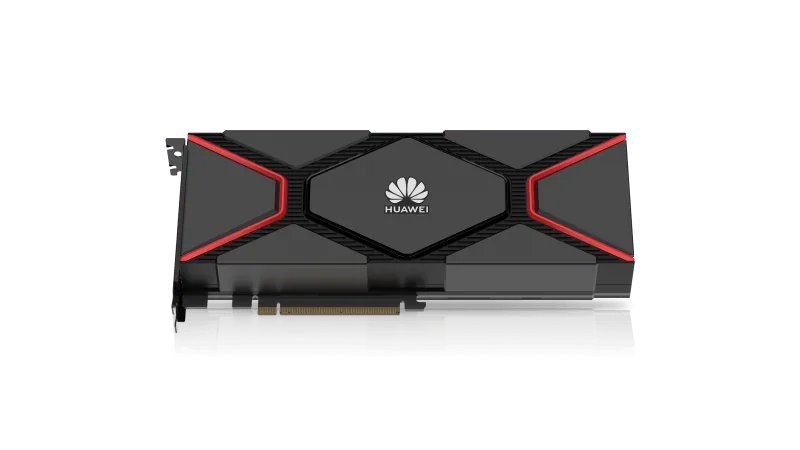
Huawei Atlas
Atlas 300I A2 Inference Card
High-performance AI inference card integrated into servers View details →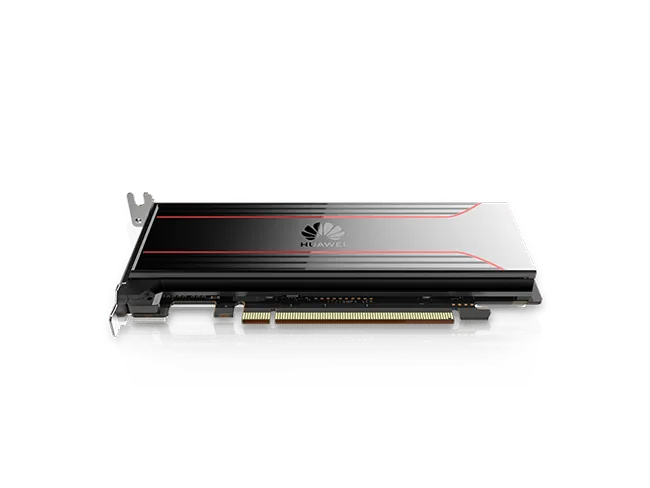
Huawei Atlas